In my uo-request-generator project, a resident describes a household problem, and the application prepares a maintenance request for the building management company. The model turns a conversational message into a concise, clear description. The user submits the request themselves.1
While preparing the public beta, I faced a narrower task: preventing the model from turning an observation into an unsupported technical demand. A report that the lights are not working does not establish what has failed or which parts need replacing.
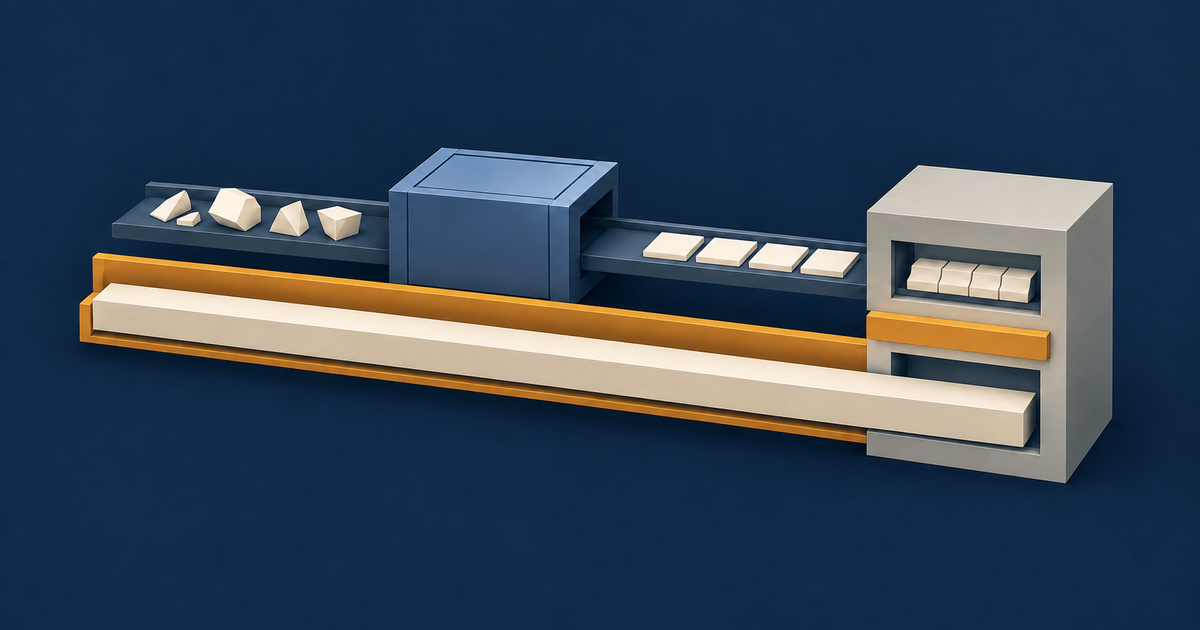
The solution involved more than checking the response. I had to decide which parts of the request the model should create at all. The description remained generative, while ordinary code took over the item specifying what the management company is asked to do.
Correct structure does not prove correct meaning
Structured Outputs constrains a response with a JSON schema: fields, types, and allowed values. This is stronger than asking for JSON, but it does not verify the truth of the content. OpenAI’s documentation explicitly states that structured responses can still contain mistakes. Model refusals and incomplete responses also need separate handling.2
Consider a hypothetical example, not the result of an actual run. The user writes:
Water is dripping from the ceiling in the shared hallway.
The model could return “Water is dripping from the ceiling in the shared hallway” in the problem field. Or it could return “Roof damage is causing a ceiling leak in the shared hallway.”
Both values satisfy a schema that only requires a non-empty string within a length limit. The second introduces a cause the user has not established. A string type check cannot distinguish it from a reported fact.
The same problem applies to requested actions. “Replace the damaged section of roofing” can pass structural validation while being an invented repair method. So I had to separate “Does the response match the schema?” from “What authorizes this component to formulate that request?”
An exact quote does not solve the whole problem either
One intermediate proposal used a fixed set of procedural roles. The model would choose operations such as identifying the cause, resolving the problem, and checking the result. It would justify those choices with exact excerpts from the user’s input, and the application would assemble the text from those decisions.
In the historical version of the architecture decision record (ADR), this approach has the status Proposed. It cannot be described as a safeguard that was already operating in a public service.3
The idea limited arbitrary text in the requested actions. But the model still made a semantic decision: which excerpt belonged to which operation, and whether it was sufficient to justify that choice.
The same ADR examines a synthetic example:
The hinges are working; the handle is missing.
A check can prove that “hinges” and “handle” occur in the original message. But if the model selects “hinges” as the missing part, an exact match does not make that choice correct. That requires understanding negation and the relationships between parts of the sentence.
Text provenance answers “Where did this excerpt come from?” It does not, by itself, answer “Is it valid to use it in this role?”
Explicit user requests posed another difficulty. If the model splits a compound action into fragments and assigns them to stages, preserving every condition and negation needs separate verification. Each selected fragment may be verbatim, while the request assembled from them is incomplete.
We removed part of the task instead of adding more checks
The beta adopted a simpler contract. In one call, the model returns descriptive fields, the problem category, warnings, and the processing outcome. Its output schema has no requested-action items. The current ADR records this decision, implemented in PR #246.4
The application creates exactly one item in the “Прошу:” (“I request:”) section. If the user fills in the separate desiredActions field, the application uses its entire validated text. If the field is absent, it inserts the generic wording “Устранить наблюдаемую проблему” (“Resolve the observed problem”).
The key choice in the implementation looks like this:5
function buildRequestItems(input: GenerateRequestInput): [string] {
  return [
    input.desiredActions === undefined
      ? PRIMARY_REQUEST_GENERIC_ITEM
      : normalizeAuthoritativeRequestItem(input.desiredActions),
  ];
}
Normalization changes presentation without changing meaning. It trims surrounding whitespace and one leading “Прошу:” prefix, replaces line breaks with spaces, and safely capitalizes the first letter. It neither shortens the text nor assigns it to roles. When assembling the result, the application adds item formatting and terminal punctuation where needed.
The tests include this request, translated here into English:
Only carry out an inspection; do not perform any work yet.
It must remain the only item. Automatically adding “Resolve the observed problem” alongside it would change an explicit constraint. The generic item is therefore used only when desiredActions is absent.
One item does not necessarily mean one simple action. A request to locate the source of water, address the cause, and then verify that the leak has stopped is preserved in full. The application does not try to decide where inspection ends and remediation begins.
This choice has a cost: without an explicit user request in the separate field, the result is less specific. But building this item no longer requires trusting the model to choose a repair method or preserve the parts of a compound action.
The word authoritative in the function name does not mean the user is technically correct. Their text is the source of what they want preserved, not proof that the proposed repair is appropriate.
The model response has no field for replacing the requested action
The separation is enforced in the data flow, beyond the prompt. The model’s output schema contains descriptive fields but no requestItems. The schemas reject extra fields. The materializePrimaryRequestDraft function receives the validated input and model response separately, then builds the internal request.65
This creates two paths:
user input → LLM → schema-validated descriptive fields

validated desiredActions or generic wording → the single “I request:” item
When the internal object is assembled, requestItems comes from the second path. The application does not ask the model to generate this field and then confirm that it changed nothing.
This provides a specific structural guarantee: the model’s output is not the source of the requested-action item the application creates. The guarantee applies to that item, not to the entire request. An unsupported repair recommendation can still appear in the generated description. I return to that boundary below.
The application owns the legal text, but classification remains a risk
Legal grounds follow a similar separation. Module texts are prepared in advance and stored in code. The model neither receives them for rewriting nor returns a selected law. It classifies the problem and supplies excerpts from the original input.1
The application adds a specific legal module only when several conditions hold: the user explicitly confirmed the subject, the model’s classification matches that confirmation, and every quote occurs verbatim in the specified source field. Without confirmation, with a mismatched subject, or with an unverifiable quote, the specific module is omitted.7
This does not establish that ordinary code has proven legal applicability. Quote validation still checks provenance. If the user and model make the same classification mistake and the quotes occur in the input, these conditions alone will not detect the error.
The boundary is narrower: the model does not write the legal paragraph, and the application does not include it without the required supporting evidence. The project maintainer remains responsible for the correctness and upkeep of the legal texts themselves. Whether the classification is semantically appropriate needs separate evaluation.
This distinction prevents a probabilistic decision from being hidden behind the name of a deterministic function. A function can map a category to a module perfectly even when the category is wrong.
Controlled rejection has a defined scope
The application does not present an invalid or partial model response as a finished request. Exceeding the output length limit also causes rejection rather than silently truncating the requested action. The contract and tests enforce this behavior.15
But omitting a specific legal module does not necessarily mean rejecting the whole request. If the remaining conditions hold, the text can be assembled without it. A safeguard should stop the particular action whose preconditions have not been met.7
Saying “the system fails closed” explains little without naming the boundary: an invalid draft is rejected, an unconfirmed module is omitted, and a user request is not cut short to produce a successful response.
None of these checks promises to detect every semantic error in the description. Structurally valid text can pass through and still be wrong in substance.
The generative part still needs evaluation
Removing free-form wording entirely would discard the model’s main purpose. This project uses it to turn a household problem report into natural, clear language. Different formulations are acceptable as long as they preserve the facts and meaning. The documentation records this principle explicitly.8
The checks therefore have separate responsibilities. Ordinary tests protect what the application enforces in code: the source of the requested-action item, preservation of conditions and negations, absence of an extra generic item, and the rules for including a legal module. Live evaluations and separate semantic review examine the remaining generative risks: invented details, lost facts, contradictions, and inappropriate warnings.59
A successful run on a set of examples does not prove that every future input will be handled without errors. It provides evidence about the behavior of a particular model and application version on the scenarios tested.
For me, the result of this work is a more precise division of responsibility, not a way to eliminate all LLM errors. Where the application can guarantee that an explicit user request is preserved, there is no reason to pass it through generation and then try to prove that its meaning survived.
Before extending a schema, I now find it more useful to ask why the model needs to make that decision at all. Sometimes the more reliable choice is to remove a field from its response rather than teach it to fill that field better.
Project README at the revision discussed. This article describes the implementation prepared for the public beta, not operational results from a public service. ↩︎ ↩︎ ↩︎
OpenAI: Structured model outputs, sections on schema adherence, refusals, and content errors. ↩︎
Intermediate ADR-0004 with Proposed status. The hinges-and-handle example comes from the Exact evidence section. ↩︎
Requested-action construction in packages/core, text assembly, and regression tests. The example requests come from synthetic tests, not residents’ submissions. ↩︎ ↩︎ ↩︎ ↩︎
Condition checks and legal module selection, functions
inputEvidenceMatchesandevaluateSpecificLegalBasisSelection. ↩︎ ↩︎Live LLM regression evaluation and semantic review process. ↩︎